What people actually mean by AI clipping
The search phrase sounds like a request for a button. Press it, get twenty vertical clips out of a webinar, post them, watch the numbers.
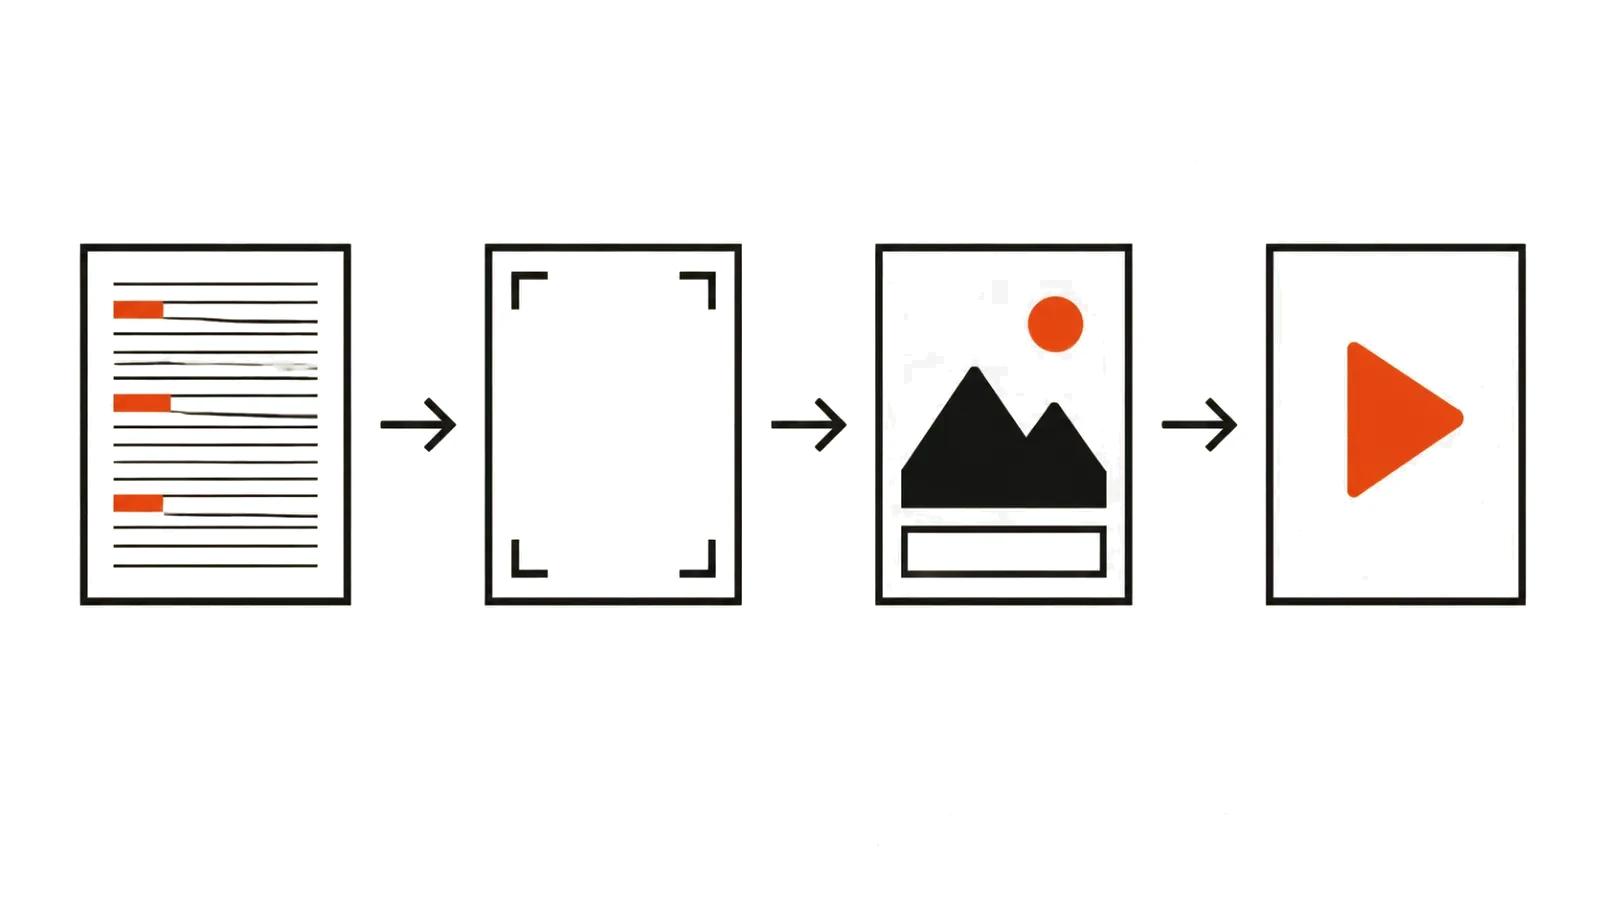
That is not how it works, and the models are not the reason. Splitting a long video into shorts is three jobs bundled into one word: find the moment, rebuild it into a complete thought, and package it for a vertical screen. The first job is machine work. The second and third are still human.
People search for a tool. What they need is an outcome: clips that get watched to the end.
What automation does well
Here is the good news: the most time-expensive part really is automatable. That part is search.
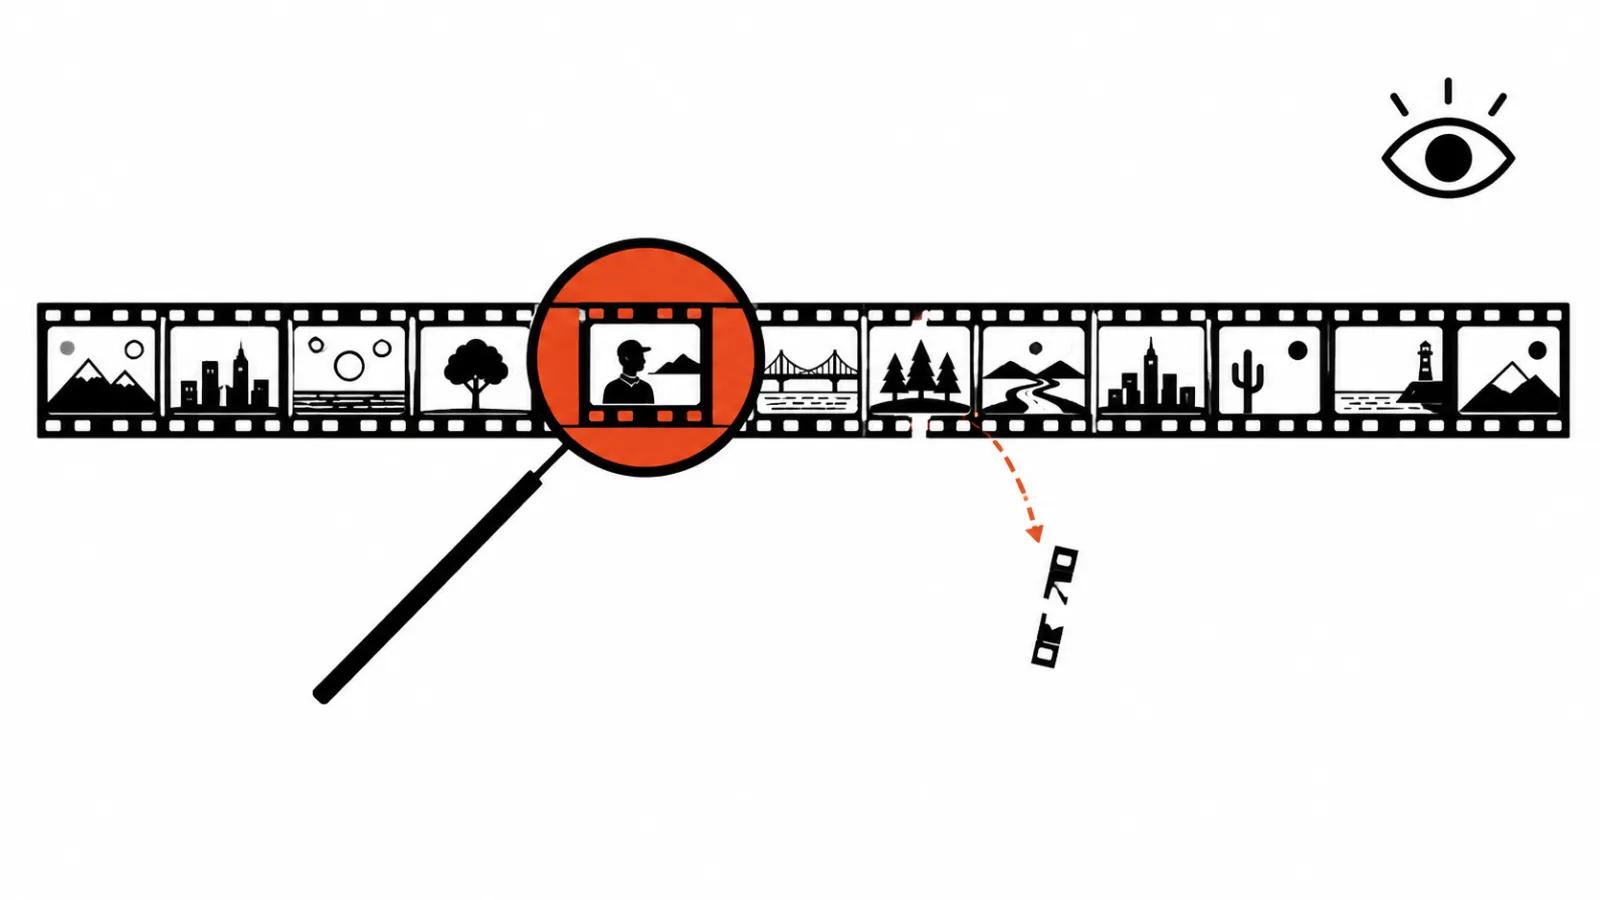
The model reads the transcript and speaker segmentation, then looks for stretches that hold attention: a topic change, a question from the room, an argument, a number, a story with a beginning and an end. Then it cuts on phrase boundaries and hands back a list of candidates with timecodes.
What a machine does better than an editor at the end of a shift:
The saving is measured in viewing hours. An editor hunting moments in a two-hour podcast spends half a shift on it.
- it watches the full two hours without skipping and without fatigue;
- it marks ten recordings the same way, which matters when the format repeats;
- it runs a fast second pass when you need five more moments from a different theme.
Where automated clipping breaks
Now the honest part about defects.
First, the phrase gets cut mid-thought. Models cut on silence, and people pause before the important word. The clip opens on "and that is why", and the viewer leaves at second two.
Second, reframing. Face tracking works while there is one speaker and even light. Two hosts, a slide on screen, handheld footage and someone who stands up and walks all break the vertical crop. You get half a face or an empty corner.
Third, the opening frame. Automation picks a frame from the start of the segment. A good hook is almost always something else: a reaction, a gesture, a number on the whiteboard.
Fourth, captions. Speech recognition mangles terminology, names and numbers. Every line needs a check, especially around money and deadlines.
The rule I work by: the machine proposes, the person approves. Clipping without review is fine for an internal archive and nothing else.
Test a service in one evening
Do not judge a demo built on someone else's clean footage. Take your most awkward recording: two speakers, room noise, a screen, interruptions. Then run five checks.
If finishing takes longer than cutting by hand, the tool is not for you, however smart the marketing looks.
- Segment boundaries. Does the clip start where the thought starts and end where it ends.
- Vertical crop. Are faces intact, does the slide stay in frame.
- Terminology. How many errors in captions on your own vocabulary.
- Manual repair. How long does finishing one clip to publishable state take.
- Second pass. Will it produce different moments if you ask for ten more.
How clipping differs from vertical videos for business
These are different genres, and mixing them up costs money.
Clipping works on footage that already exists: a podcast, an interview, a webinar, a lecture. The job is to keep the meaning and not lose the context.
Vertical videos for business are usually built from scratch for a specific task: a product, an offer, a seasonal campaign. There is no two-hour source file, there is a brief.
What they share is the opening frame and the pacing. If you are clipping for a company account, look at how vertical videos for business are structured so you do not reinvent the format. The retention logic carries over almost unchanged.
AI video production covers the draft layer in this setup: transcript, candidate search, rough captions. Final assembly stays manual, and that is fine. Vertical video ads are a separate case: there the first frame and pacing outweigh any effect, so a clipped fragment only works as raw material.
When clipping is the wrong answer
Sometimes there is no source footage and clips are still needed. Then the question is editing from whatever exists: phone footage, screen recordings, call recordings made with permission.
A different class of tool helps here, a video agent for editing that assembles a sequence from scattered files based on a description of the task. That is not about finding moments in a long recording, it is about building a scene from fragments.
Another case: the material exists but it was never built for vertical. A twenty-minute horizontal film will not split into shorts without losing something, because the drama works on a different scale. Clipping does not rescue a format that was never designed for a small screen.
What I do in practice
The order is fixed.
Transcript first, so I know what the recording is about. Then automated candidate search, twenty for two hours. Then a manual pass that keeps five. Then manual reframing and opening frames. Then captions with a proofread. Then publishing, then looking at retention.
The last step is where the real information shows up: which of the five worked. The next batch is built around that type of moment. Automation shortens the loop, statistics makes the choice.
For a steady stream of mass vertical videos the logic inverts: repeatability and volume matter more than finding one lucky moment.